%%{init: { "theme": "base", "themeVariables": { "git0": "#dc2626", "git1": "#2563eb", "gitBranchLabel0": "#ffffff", "gitBranchLabel1": "#ffffff", "commitLabelColor": "#1e293b", "commitLabelBackground": "#f1f5f9" } } }%%
gitGraph
   commit id: "data-added"
   branch set-up-venv
   checkout set-up-venv
   commit id: "init uv"
   checkout main
   merge set-up-venv id: "merge PR"
Reproducible Environments
If you get hit by a bus today, will your colleagues be able to run your project tomorrow?
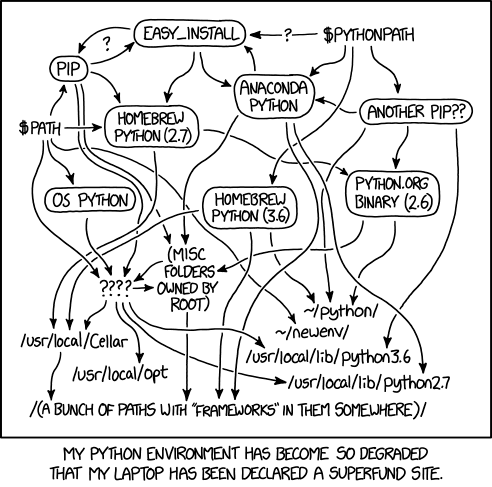
In Session 1, you created an empty repository, documented its purpose, added raw literature data from Project Gutenberg, and practiced collaborative Git workflows. Your project had a clean but flat structure: a README.md and plain-text book files.
In this session, you will turn that raw repository into a reproducible research project. You will declare a pinned Python environment, experience and resolve an undeclared dependency, perform a controlled data overwrite to motivate strict directory boundaries (data/raw/, data/intermediate/, scripts/), refactor counting logic into a reusable Python package (src/bookstats/), and launch an interactive Marimo visualization.
NoteRecovery Checkpoints
If you need to catch up or compare your project against the canonical reference repository (bookstats), you can inspect the milestone tags:
- Tag
venv-declared: Python 3.12 pinned,pyproject.toml,uv.lock,.gitignore. - Tag
word-counting:count_words.pystarter script,polarsdeclared dependency. - Tag
data-separated:data/raw/,data/intermediate/,scripts/separation. - Tag
bookstats-package:src/bookstats/package layout,counts.py,notebooks/visualize.pywith Marimo & Altair.
Learning Outcomes
By the end of this one-hour session, you will be able to:
- Pin Python 3.12 and initialize a reproducible environment inside an existing repository using
uv. - Inspect and explain the role of
.python-version,pyproject.toml,uv.lock, and.gitignore. - Experience a missing dependency error and resolve it cleanly with
uv add. - Refactor exploratory scripts into a reusable
src/package layout (src/bookstats/). - Try Marimo via
uvxand run an interactive visualization notebook connected to intermediate book counts.
Choose Any Project Gutenberg Books: In the examples below, we demonstrate commands using Mary Shelley’s Frankenstein (00084_frankenstein.txt) and Bram Stoker’s Dracula (00345_dracula.txt). Feel free to analyze those or replace them with any books you and your partner selected in Session 1!
Declaring the Environment (set-up-venv)
Why Virtual Environments?
In scientific computing, different projects often require different versions of libraries (for example, Polars 1.x vs 0.20, or PyTorch 2.2 vs 2.1). If you install all packages into a single global Python installation, upgrading a package for one project will inevitably break another.
A virtual environment is an isolated folder (conventionally named .venv/) containing a dedicated Python executable and installed packages for a single project.
Why uv?
Astral uv is a fast, modern Python package and project manager written in Rust. It replaces pip, venv, pip-tools, and poetry with a unified tool that: - Pins the project’s exact Python interpreter version. - Resolves and downloads packages in milliseconds. - Generates a universal lock file (uv.lock) for cross-platform reproducibility. - Automatically handles virtual environment creation and execution without requiring constant manual shell activation.
Create the Feature Branch
In VS Code: 1. Open your bookstats repository. 2. Click the branch indicator in the bottom-left Status Bar (or open the Source Control panel). 3. Select Create Branch… and name it set-up-venv.
TipTerminal equivalent
git checkout -b set-up-venvPin Python 3.12 and Initialize uv
Open the VS Code Integrated Terminal (Ctrl+\`` orCmd+``). Make sure you are in your project root:
uv python pin 3.12Pinned `.python-version` to `3.12`Now initialize the project manifest in place without overwriting existing files:
uv init --bareInitialized project `bookstats`
NoteWhy –bare?
The --bare flag creates only the packaging manifest (pyproject.toml) and avoids generating sample boilerplate files (like hello.py) inside an existing repository.
Inspect the newly created files in the VS Code Explorer: - .python-version: contains 3.12. It informs uv which Python interpreter must be used for this project. If Python 3.12 is not installed on your system, uv will automatically download an isolated, standalone build of Python 3.12 on demand! - pyproject.toml: the standardized project manifest defining metadata, Python requirements, and dependencies.
Inspect and Update pyproject.toml
Open pyproject.toml in VS Code. It will look like this:
[project]
name = "bookstats"
version = "0.1.0"
description = "Add your description here"
readme = "README.md"
requires-python = ">=3.12"
dependencies = []
Update the description to describe your scientific goal:
description = "A cumulative research project analyzing Project Gutenberg word distributions"Notice dependencies = []. It is currently empty because we have not declared any third-party packages yet.
Ensure .venv/ is Ignored by Git
Look at your .gitignore file. If uv init did not create one or if .venv is missing, open .gitignore and ensure it includes:
.venv/
__pycache__/
*.pyc
ImportantWhy Must
.venv/ Never Be Committed to Git?
- Size: A virtual environment can contain thousands of files totaling hundreds of megabytes.
- Platform Specificity: Binaries, symlinks, and dynamic libraries inside
.venv/are compiled specifically for your operating system and CPU architecture (e.g. macOS ARM64 vs Linux x86_64). Committing.venv/will break the project for collaborators on different platforms. - Reproducibility: We commit the declarations (
pyproject.tomlanduv.lock), not the artifacts (.venv/). Anyone can recreate the exact environment on any computer withuv sync.
Create and Test the Environment
Tell uv to resolve dependencies and build the virtual environment:
uv syncResolved 1 package in 2ms
Prepared 1 package in 1ms
Installed 1 package in 1ms
+ bookstats==0.1.0 (from file://...)Notice two new items: 1. uv.lock: A generated lock file recording exact package versions, hashes, and platform markers. uv.lock must be committed to Git. 2. .venv/: The local virtual environment directory (greyed out in VS Code Explorer because it is ignored).
Let’s activate and deactivate the environment once in your terminal to understand how traditional activation works:
source .venv/bin/activateNotice the prompt prefix changes: (bookstats) $. You can check which Python executable is currently active:
which python.../bookstats/.venv/bin/pythonNow deactivate it:
deactivateThe (bookstats) prefix disappears. With uv, you will rarely need to activate environments manually because uv run handles execution transparently.
Configure VS Code’s Python Interpreter
To ensure VS Code provides autocomplete, linting, and type checking using your project environment: 1. Press Cmd+Shift+P (macOS) or Ctrl+Shift+P (Windows/Linux) to open the Command Palette. 2. Type and select Python: Select Interpreter. 3. Choose the option labeled ('.venv': venv) .venv/bin/python.
VS Code will remember this setting in your workspace.
Commit, Push, Review, and Merge
Check your changes in the VS Code Source Control panel: - Staged/Untracked: .python-version, pyproject.toml, uv.lock, .gitignore.
Stage all changes.
Commit with message:
chore: pin python 3.12 and initialize uv environment.Publish/push the branch to GitHub:
git push -u origin set-up-venvOn GitHub, open a pull request titled “Set up virtual environment with uv”.
Review the diff (verify
.venvis NOT in the PR!).Merge using Create a merge commit.
Delete the remote branch on GitHub.
In VS Code, switch back to
main, pull the merge commit (git pull origin main), and delete the localset-up-venvbranch (git branch -d set-up-venv).
Adding Word Counting Script (add-word-counting)
Create the Feature Branch
%%{init: { "theme": "base", "themeVariables": { "git0": "#dc2626", "git1": "#2563eb", "gitBranchLabel0": "#ffffff", "gitBranchLabel1": "#ffffff", "commitLabelColor": "#1e293b", "commitLabelBackground": "#f1f5f9" } } }%%
gitGraph
   commit id: "venv-declared"
   branch add-word-counting
   checkout add-word-counting
   commit id: "add count_words"
   checkout main
   merge add-word-counting id: "merge PR"
In VS Code: 1. Create and switch to branch add-word-counting: bash git checkout -b add-word-counting
Add the Word Counting Script
- In VS Code, create a new file named
count_words.pyin the root of yourbookstatsrepository. - Open
count_words.pyon GitHub to copy the code, or expand the box below and click the Copy icon:
NoteExpand to view and copy count_words.py
"""Count word frequencies in a plain-text book and save results to CSV.

Usage:
    python count_words.py INPUT OUTPUT

Example:
    python count_words.py 00084_frankenstein.txt 00084_frankenstein.csv
"""

import re
import sys
from pathlib import Path
import polars as pl


def strip_gutenberg_headers(text: str) -> str:
    """Strip Project Gutenberg header and footer licenses from text if present."""
    start_match = re.search(r"\*\*\* START OF THE PROJECT GUTENBERG EBOOK[^\n]*\*\*\*", text)
    if start_match:
        text = text[start_match.end():]
    end_match = re.search(r"\*\*\* END OF THE PROJECT GUTENBERG EBOOK", text)
    if end_match:
        text = text[:end_match.start()]
    return text


def extract_words(text: str) -> list[str]:
    """Extract and normalize lowercase words from a text string."""
    cleaned = strip_gutenberg_headers(text)
    return re.findall(r"\b[a-zA-Z]+\b", cleaned.lower())


def count_words(words: list[str]) -> pl.DataFrame:
    """Count occurrences of each word and sort by frequency descending."""
    if not words:
        return pl.DataFrame({"word": [], "count": []}, schema={"word": pl.String, "count": pl.UInt32})
    df = pl.DataFrame({"word": words})
    return (
        df.group_by("word")
        .agg(pl.len().alias("count"))
        .sort("count", descending=True)
    )


def main():
    if len(sys.argv) != 3:
        print(__doc__)
        sys.exit(1)

    input_path = Path(sys.argv[1])
    output_path = Path(sys.argv[2])

    if not input_path.exists():
        print(f"Error: Input file '{input_path}' not found.", file=sys.stderr)
        sys.exit(1)

    text = input_path.read_text(encoding="utf-8")
    words = extract_words(text)
    counts = count_words(words)

    output_path.parent.mkdir(parents=True, exist_ok=True)
    counts.write_csv(output_path)
    print(f"Wrote {len(counts)} unique word counts to {output_path}")


if __name__ == "__main__":
    main()
Paste the code into count_words.py and save the file. Notice line 13: import polars as pl.
Run the Script
Run the script inside your project using uv run:
uv run python count_words.py 00084_frankenstein.txt 00084_frankenstein.csvThe command fails with a ModuleNotFoundError:
Traceback (most recent call last):
  File ".../count_words.py", line 13, in <module>
    import polars as pl
ModuleNotFoundError: No module named 'polars'
The script requires polars, but it is not yet declared in pyproject.toml.
Declare and Resolve the Dependency
Use uv add to declare polars:
uv add polarsResolved 6 packages in 120ms
Prepared 6 packages in 250ms
Installed 6 packages in 15ms
+ polars==1.x.x
+ pyarrow==...Look at what changed: 1. Open pyproject.toml: toml dependencies = [ "polars>=1.x.x", ] 2. Open uv.lock: uv recorded the exact version of Polars and all its dependencies, along with cryptographic hashes.
Noteuv resolves and syncs automatically
Unlike older tools where you ran pip install polars and then manually remembered to run pip freeze > requirements.txt, uv add updates pyproject.toml, locks the versions in uv.lock, and installs them into .venv/ in one atomic operation.
Run the Script Successfully
Now run the script using uv run:
uv run python count_words.py 00084_frankenstein.txt 00084_frankenstein.csv(Or substitute your chosen book’s .txt filename).
Wrote 7055 unique word counts to 00084_frankenstein.csvOpen 00084_frankenstein.csv in VS Code. You will see word frequencies sorted from most common to least common:
word,count
the,4187
and,2973
i,2848
of,2643
to,2093
my,1771
a,1579
in,1427
was,1018
...
Commit, Push, Review, and Merge
Remove the generated CSV file before committing (we will organize outputs properly in the next step):
rm *.csvStage
count_words.py,pyproject.toml, anduv.lock.Commit:
feat: add word-counting script and declare polars dependency.Push to GitHub:
git push -u origin add-word-countingOpen a pull request: “Add word-counting script with Polars dependency”.
Review and merge via Create a merge commit.
Switch to
main, pull, and delete theadd-word-countingbranch locally.
Separating Data from Code (separate-data)
Right now, our repository root has raw books (00084_frankenstein.txt), Python scripts (count_words.py), and configuration files all mixed together. When analysis scripts generate intermediate tables, where should they go?
Let’s see what happens when inputs and outputs are not cleanly separated.
The Controlled Overwrite Exercise
Imagine you or a collaborator make a small typo in the terminal and accidentally supply the input raw text path as the output CSV path:
# DO NOT PANIC: This is a controlled demonstration of Git recovery!
uv run python count_words.py 00084_frankenstein.txt 00084_frankenstein.txt
Now open 00084_frankenstein.txt in VS Code!
The novel has been overwritten by CSV comma-separated word counts! If this were uncommitted research data on a shared drive without version control, your raw data would be permanently destroyed.
Restoring Raw Data with Git
Because our raw book was committed to Git in Session 1, recovery takes one click:
- Open the Source Control panel in VS Code (
Ctrl+Shift+GorCmd+Shift+G). - Under Changes, locate
00084_frankenstein.txt. - Hover over the file and click the Discard Changes icon (the circular undo arrow \(\mathbf{\hookleftarrow}\)).
- Confirm Discard Changes.
Open 00084_frankenstein.txt again. Mary Shelley’s novel is completely restored!
TipTerminal equivalent
git checkout HEAD -- 00084_frankenstein.txt
# Or in modern Git:
git restore 00084_frankenstein.txt
The Solution: Explicit Directory Boundaries
To prevent accidents and clarify data provenance, scientific software adheres to strict folder conventions:
bookstats/
├── data/
│   ├── raw/           # READ-ONLY original source data (never edited or overwritten)
│   └── intermediate/  # Generated data tables (can be deleted and reproduced anytime)
└── scripts/           # Standalone executable scripts
Create the Feature Branch
%%{init: { "theme": "base", "themeVariables": { "git0": "#dc2626", "git1": "#2563eb", "gitBranchLabel0": "#ffffff", "gitBranchLabel1": "#ffffff", "commitLabelColor": "#1e293b", "commitLabelBackground": "#f1f5f9" } } }%%
gitGraph
   commit id: "word-counting"
   branch separate-data
   checkout separate-data
   commit id: "separate data"
   checkout main
   merge separate-data id: "merge PR"
In VS Code: 1. Open the Source Control panel (or bottom-left branch indicator). 2. Create and switch to branch separate-data:
git checkout -b separate-dataCreate Directories and Move Files
In VS Code Explorer (or terminal): 1. Create folders: data/raw, data/intermediate, and scripts. 2. Move all .txt book files into data/raw/. 3. Move count_words.py into scripts/.
TipTerminal equivalent
mkdir -p data/raw data/intermediate scripts
mv *.txt data/raw/
mv count_words.py scripts/
Check git status: Git automatically tracks file renames without losing history!
Run the Script with Clear Separation
Run the script reading from data/raw/ and writing to data/intermediate/:
uv run python scripts/count_words.py data/raw/00084_frankenstein.txt data/intermediate/00084_frankenstein.csvProcess your second book as well (e.g. Dracula):
uv run python scripts/count_words.py data/raw/00345_dracula.txt data/intermediate/00345_dracula.csvBoth intermediate count files are now neatly isolated in data/intermediate/.
Ignore Generated Intermediate Data
Intermediate files are derived artifacts that can be regenerated at any time by running our script. We do not want them cluttering Git diffs.
Add data/intermediate/ to your .gitignore:
.venv/
__pycache__/
*.pyc

# Generated data artifacts
data/intermediate/
data/processed/
Inspect the Project Tree
In VS Code Explorer, expand the folders. Your project structure now looks like:
bookstats/
├── .gitignore
├── .python-version
├── pyproject.toml
├── uv.lock
├── README.md
├── data/
├── data/raw/
│   ├── 00084_frankenstein.txt
│   └── 00345_dracula.txt
│   └── intermediate/
│       ├── 00084_frankenstein.csv
│       └── 00345_dracula.csv
└── scripts/
    └── count_words.py
NoteInspecting with tree in the terminal
If you have the tree utility installed, you can run:
tree -I ".venv|__pycache__" -L 3If not installed: - macOS (Homebrew): brew install tree - Ubuntu / Debian / WSL: sudo apt install tree
Commit, Push, Review, and Merge
Stage changes (
.gitignore, the moved files, etc.).Commit:
refactor: organize project into data/raw, data/intermediate, and scripts.Push to GitHub:
git push -u origin separate-dataOpen PR: “Separate data into raw, intermediate, and scripts directories”.
Review, merge via Create a merge commit, and delete the branch.
Switch back to
mainlocally, pull, and deleteseparate-data.
Creating a Reusable Package (create-package)
Right now, our counting logic lives inside scripts/count_words.py. If we want to reuse extract_words() and count_words() inside automated unit tests (Session 3), a data pipeline (Session 4), or an interactive visualization notebook, importing from a script inside a scripts/ directory is clumsy and error-prone.
In professional software development, reusable logic lives in a package under src/, while scripts, notebooks, and tests import from that package.
Create the Feature Branch
%%{init: { "theme": "base", "themeVariables": { "git0": "#dc2626", "git1": "#2563eb", "gitBranchLabel0": "#ffffff", "gitBranchLabel1": "#ffffff", "commitLabelColor": "#1e293b", "commitLabelBackground": "#f1f5f9" } } }%%
gitGraph
   commit id: "data-separated"
   branch create-package
   checkout create-package
   commit id: "package bookstats"
   commit id: "add marimo"
   checkout main
   merge create-package id: "merge PR"
In VS Code: 1. Open the Source Control panel (or bottom-left branch indicator). 2. Create and switch to branch create-package:
git checkout -b create-packageWhat is a Flat Layout vs. src/ Layout?
In a flat layout, Python packages sit directly in the repository root (bookstats/). While simple, it can lead to accidental imports of local working files instead of the installed package.
In a src/ layout, your package logic lives under src/bookstats/. This enforces an explicit boundary: code can only be imported if it is properly installed in the environment:
| Layout | Structure | Behavior |
|---|---|---|
| Flat Layout | bookstats/counts.py |
Imports directly from repository root, but risks namespace collisions. |
src/ Layout |
src/bookstats/counts.py |
Enforces packaging hygiene and ensures tests run against installed code. |
Build the src/ Package Structure
Create the package directory:
mkdir -p src/bookstatsCreate two files inside src/bookstats/: 1. src/bookstats/counts.py 2. src/bookstats/__init__.py
1. src/bookstats/counts.py
In VS Code, create a new file named src/bookstats/counts.py. Open counts.py on GitHub to copy the code, or expand the box below and click the Copy icon:
NoteExpand to view and copy src/bookstats/counts.py
"""Word extraction and frequency counting functions."""

from __future__ import annotations

import argparse
import re
import sys
from pathlib import Path

import polars as pl


def strip_gutenberg_headers(text: str) -> str:
    """Strip Project Gutenberg header and footer licenses from text.

    Parameters
    ----------
    text : str
        Raw text content of a Project Gutenberg book.

    Returns
    -------
    str
        Text content with license headers and footers removed.
    """
    start_match = re.search(
        r"\*\*\* START OF THE PROJECT GUTENBERG EBOOK[^\n]*\*\*\*", text
    )
    if start_match:
        text = text[start_match.end() :]
    end_match = re.search(r"\*\*\* END OF THE PROJECT GUTENBERG EBOOK", text)
    if end_match:
        text = text[: end_match.start()]
    return text


def extract_words(text: str) -> list[str]:
    """Extract and normalize lowercase words from text.

    Parameters
    ----------
    text : str
        Input text to extract words from.

    Returns
    -------
    list of str
        List of lowercased word tokens with punctuation removed.
    """
    cleaned = strip_gutenberg_headers(text)
    return re.findall(r"\b[a-zA-Z]+\b", cleaned.lower())


def count_words(words: list[str]) -> pl.DataFrame:
    """Count occurrences of each word and sort by frequency descending.

    Parameters
    ----------
    words : list of str
        List of normalized words.

    Returns
    -------
    polars.DataFrame
        DataFrame with columns 'word' and 'count', ordered from most
        frequent to least frequent.
    """
    if not words:
        return pl.DataFrame(
            {"word": [], "count": []},
            schema={"word": pl.String, "count": pl.UInt32},
        )
    df = pl.DataFrame({"word": words})
    return (
        df.group_by("word").agg(pl.len().alias("count")).sort("count", descending=True)
    )


def process_book_file(input_path: Path | str, output_path: Path | str) -> pl.DataFrame:
    """Process a single book text file and save word counts to CSV.

    Parameters
    ----------
    input_path : Path or str
        Path to the raw text input file.
    output_path : Path or str
        Destination path for the intermediate count CSV.

    Returns
    -------
    polars.DataFrame
        DataFrame of word counts that was written to disk.
    """
    in_p = Path(input_path)
    out_p = Path(output_path)
    text = in_p.read_text(encoding="utf-8")
    words = extract_words(text)
    counts = count_words(words)
    out_p.parent.mkdir(parents=True, exist_ok=True)
    counts.write_csv(out_p)
    return counts


def main() -> None:
    """Command-line interface for word counting."""
    parser = argparse.ArgumentParser(
        description="Count word frequencies in Project Gutenberg books."
    )
    parser.add_argument(
        "input",
        help="Input text file path.",
    )
    parser.add_argument(
        "output",
        help="Output CSV file path.",
    )

    args = parser.parse_args()
    process_book_file(args.input, args.output)
    print(f"Processed {args.input} -> {args.output}")


if __name__ == "__main__":
    main()
Paste the code into src/bookstats/counts.py and save the file.
2. src/bookstats/__init__.py
In VS Code, create a new file named src/bookstats/__init__.py. This file exports the public API of your package:
"""bookstats: A reproducible analysis package for Gutenberg word frequencies."""

from bookstats.counts import (
    count_words,
    extract_words,
    process_book_file,
    strip_gutenberg_headers,
)

__all__ = [
    "strip_gutenberg_headers",
    "extract_words",
    "count_words",
    "process_book_file",
]
NoteWhat is an API?
In software development, an Application Programming Interface (API) is the formal contract defining how external programs communicate with your package.
In Python, a package folder can contain dozens of internal helper files, variables, and private functions. Without an explicit boundary, users of your library would have to import directly from deep implementation files (from bookstats.counts import count_words), tightly coupling their code to your internal folder structure.
Configure pyproject.toml for the src/ Layout
To make bookstats installable in editable mode by uv, add the build system specification to pyproject.toml:
[build-system]
requires = ["hatchling"]
build-backend = "hatchling.build"
Then synchronize the environment so uv registers your package:
uv syncInstalled 1 package in 2ms
+ bookstats==0.1.0 (from file://...)Now test running the package directly via Python’s module flag (-m):
uv run python -m bookstats.counts data/raw/00084_frankenstein.txt data/intermediate/00084_frankenstein.csvProcessed data/raw/00084_frankenstein.txt -> data/intermediate/00084_frankenstein.csvProcess your second book as well:
uv run python -m bookstats.counts data/raw/00345_dracula.txt data/intermediate/00345_dracula.csv
TipAutomating Batch Processing
Running each book manually works for two books, but what if you have dozens? In Session 4, we will use GNU Make to automate batch counting across all books with dependency tracking.
Interactive Visualization with Marimo
Now that our package produces structured count data in data/intermediate/, let’s explore it interactively!
Instead of traditional Jupyter notebooks (which save binary outputs, execution counts, and JSON diffs that pollute Git), we use Marimo. Marimo notebooks are stored as pure Python scripts, making them 100% Git-friendly, reproducible, and reactive.
Step 1: Try Marimo in a Quick Sandbox (uvx)
Before adding new dependencies to your project, you can try Marimo immediately in an isolated sandbox using uvx:
uvx marimo tutorial plotsThis runs Marimo’s built-in plotting tutorial in your browser without altering your project environment. Feel free to interact with the sliders and charts! When you are ready, return to your terminal and press Ctrl+C to stop the tutorial server.
Step 2: Install Marimo and Altair
Add marimo and altair to your project dependencies:
uv add marimo altairStep 3: Create notebooks/visualize.py
Create a directory named notebooks:
mkdir -p notebooksIn VS Code, create a new file named notebooks/visualize.py. Open visualize.py on GitHub to copy the code, or expand the box below and click the Copy icon:
NoteExpand to view and copy notebooks/visualize.py
import marimo

__generated_with = "0.11.0"
app = marimo.App(width="medium")


@app.cell
def __():
    from pathlib import Path
    import altair as alt
    import marimo as mo
    import polars as pl

    return mo, alt, pl, Path


@app.cell
def __(mo):
    mo.md(
        r"""
        # Book Word Frequency Analysis

        An interactive visualization of word frequency distributions across Project Gutenberg books.
        """
    )
    return


@app.cell
def __(Path, pl):
    # Load processed book counts
    processed_path = Path("data/processed/book-counts.csv")
    if processed_path.exists():
        counts_df = pl.read_csv(processed_path)
    else:
        # Fallback to intermediate counts if processed is not yet generated
        intermediate_dir = Path("data/intermediate")
        csv_files = list(intermediate_dir.glob("*.csv"))
        if csv_files:
            frames = []
            for p in csv_files:
                d = pl.read_csv(p).with_columns(pl.lit(p.stem).alias("book"))
                frames.append(d.select(["book", "word", "count"]))
            counts_df = pl.concat(frames)
        else:
            counts_df = pl.DataFrame(
                {"book": [], "word": [], "count": []},
                schema={"book": pl.String, "word": pl.String, "count": pl.UInt32},
            )
    return counts_df, processed_path


@app.cell
def __(counts_df, mo):
    books = (
        sorted(counts_df["book"].unique().to_list())
        if len(counts_df) > 0
        else ["None"]
    )
    book_selector = mo.ui.dropdown(
        options=books,
        value=books[0] if books else "None",
        label="Select a book:",
    )
    book_selector
    return book_selector, books


@app.cell
def __(alt, book_selector, counts_df, mo, pl):
    mo.stop(book_selector.value == "None", mo.md("No books available."))

    selected_df = (
        counts_df.filter(pl.col("book") == book_selector.value)
        .sort("count", descending=True)
        .head(30)
    )

    chart = (
        alt.Chart(selected_df)
        .mark_bar()
        .encode(
            x=alt.X("count:Q", title="Frequency Count"),
            y=alt.Y("word:N", sort="-x", title="Word"),
            tooltip=["word", "count"],
        )
        .properties(
            title=f"Top 30 Most Frequent Words: {book_selector.value}",
            width=600,
            height=500,
        )
    )

    mo.ui.altair_chart(chart)
    return chart, selected_df


if __name__ == "__main__":
    app.run()
Paste the code into notebooks/visualize.py and save the file.
How the Notebook Works: 3 Reactive Building Blocks
Notice how Marimo structures the interactive script:
Cell Dependencies and Returns:
@app.cell
def __():
    from pathlib import Path
    import altair as alt
    import marimo as mo
    import polars as pl
    return mo, alt, pl, Path
Each cell is a pure function. Marimo parses variable definitions and returns, constructing a Directed Acyclic Graph (DAG) of cell dependencies—just like formulas in a spreadsheet!
Interactive UI Widgets (
mo.ui):book_selector = mo.ui.dropdown( options=books, value=books[0] if books else "None", label="Select a book:", ) book_selectorDisplaying
book_selectorrenders a dropdown element directly in your browser. Whenever a user chooses a different book, Marimo automatically triggers downstream cells that referencebook_selector.value.Reactive Chart Rendering (
altair):selected_df = counts_df.filter(pl.col("book") == book_selector.value).head(30) chart = alt.Chart(selected_df).mark_bar().encode( x=alt.X("count:Q", title="Frequency Count"), y=alt.Y("word:N", sort="-x", title="Word"), ) mo.ui.altair_chart(chart)When the dropdown changes, only this visualization cell re-renders, updating the Top 30 word frequencies without recalculating data from disk.
Step 4: Launch the Interactive Visualization
Run the notebook as an interactive web application:
uv run marimo run notebooks/visualize.pyMarimo will open an interactive dashboard in your default browser: - Select any analyzed book from the dropdown menu to inspect its word frequencies. - Hover over the interactive Altair bar chart to see exact counts.
TipInspecting and Editing Code Cells
To view and edit the underlying reactive code cells instead of running as a clean web app:
uv run marimo edit notebooks/visualize.pyPress Ctrl+C in your terminal when you are ready to shut down the Marimo server.
Update the Project README.md
Update your repository’s README.md to reflect the new structure and provide exact instructions so anyone can reproduce your environment and run your analysis:
# bookstats

A cumulative research project analyzing word frequency distributions across classic literature from Project Gutenberg.

## Setup Instructions

This project requires Python 3.12 and [uv](https://docs.astral.sh/uv/).

To reconstruct the virtual environment:

```bash
uv sync
To select the environment in VS Code: 1. Open Command Palette (Cmd+Shift+P / Ctrl+Shift+P). 2. Choose Python: Select Interpreter. 3. Select .venv/bin/python.
Running the Analysis
Process a raw book using the bookstats package:
uv run python -m bookstats.counts data/raw/00084_frankenstein.txt data/intermediate/00084_frankenstein.csvLaunch the interactive visualization:
uv run marimo run notebooks/visualize.py
### Commit, Push, Review, and Merge

1. Remove any legacy `scripts/count_words.py` file (its logic is now safely inside `src/bookstats/counts.py`):
   ```bash
   git rm scripts/count_words.py
   rmdir scripts
Stage all additions:
src/bookstats/,notebooks/visualize.py,pyproject.toml,uv.lock, andREADME.md.Commit:
feat: convert counting logic into bookstats package and add marimo visualization.Push to GitHub:
git push -u origin create-packageOpen PR: “Convert counting logic to bookstats package and add visualization”.
Review the pull request diff, approve, and merge with Create a merge commit.
Delete the branch on GitHub, switch to
mainlocally, pull, and deletecreate-packagelocally.
Same Practice, Different Ecosystems
While this course uses Python and uv, the principle of declaring dependencies and locking environments per project is standard across scientific computing:
| Ecosystem | Manifest File (Declared) | Lock File (Exact Resolution) | Environment Directory | Package Manager Command |
|---|---|---|---|---|
| Python | pyproject.toml |
uv.lock |
.venv/ |
uv add <pkg> / uv sync |
| R | DESCRIPTION / renv.lock |
renv.lock |
renv/library/ |
renv::init() / renv::snapshot() |
| Julia | Project.toml |
Manifest.toml |
~/.julia/environments/ |
Pkg.add("<pkg>") / Pkg.instantiate() |
Whatever programming language you use in your lab, the rule remains: never rely on unrecorded global packages. Always commit the manifest and lock files, and never commit the installed environment directory.
NoteBeyond Language Environments: Containers (Docker and Apptainer)
Language-specific tools like uv, renv, and Julia’s package manager manage packages inside their respective runtimes. However, scientific workflows often depend on system-level libraries, C/C++ compilers, CUDA drivers, or command-line binaries (e.g. samtools, blast, or graphviz).
To capture the entire operating system environment: - Docker: Widely used for local development and cloud deployments. Defines a recipe (Dockerfile) that packages an operating system, system libraries, and software into a container image. - Apptainer (formerly Singularity): Standard on High-Performance Computing (HPC) clusters (including the OIST Deigo computing cluster). Unlike Docker, Apptainer runs containers without root privileges and can seamlessly run Docker images on HPC clusters.
In Session 4, we will automate our Python project with Make and GitHub Actions; containerization builds directly upon these exact same declarative principles.
Ending-State Tree
At the conclusion of Session 2, your repository has evolved from a flat folder into a professional, reproducible research project:
bookstats/
├── .gitignore
├── .python-version
├── pyproject.toml
├── uv.lock
├── README.md
├── data/
│   ├── raw/
│   │   ├── 00084_frankenstein.txt
│   │   └── 00345_dracula.txt
│   └── intermediate/
│       ├── 00084_frankenstein.csv
│       └── 00345_dracula.csv
├── src/
│   └── bookstats/
│       ├── __init__.py
│       └── counts.py
└── notebooks/
    └── visualize.py
Transfer Task (Before Session 3)
Before our next meeting, take 20 minutes to inspect your current OIST research project:
- Identify at least one undeclared dependency (a library you import in a notebook or script that is not recorded in any setup file) or check if you have a way to reproduce your environment from scratch.
- If your project has code and data mixed in the same directory, identify where the boundary between read-only raw data and generated outputs should be.
- Bring your findings to the first 15 minutes of Session 3 for our Project Clinic.
Completion Checklist
Before moving on to Session 3, confirm that you can check off every item: